
The Honeypot That Reacts
Sources checked . Incident guidance can change; follow the linked vendor advisories.
A believable decoy, a read-only AI defense team, and a practical way to tell whether a patch took effect.
In this article (5 sections)
The office, incident and example verdict below are fictional. The design is for authorized defensive observation and offline validation only.
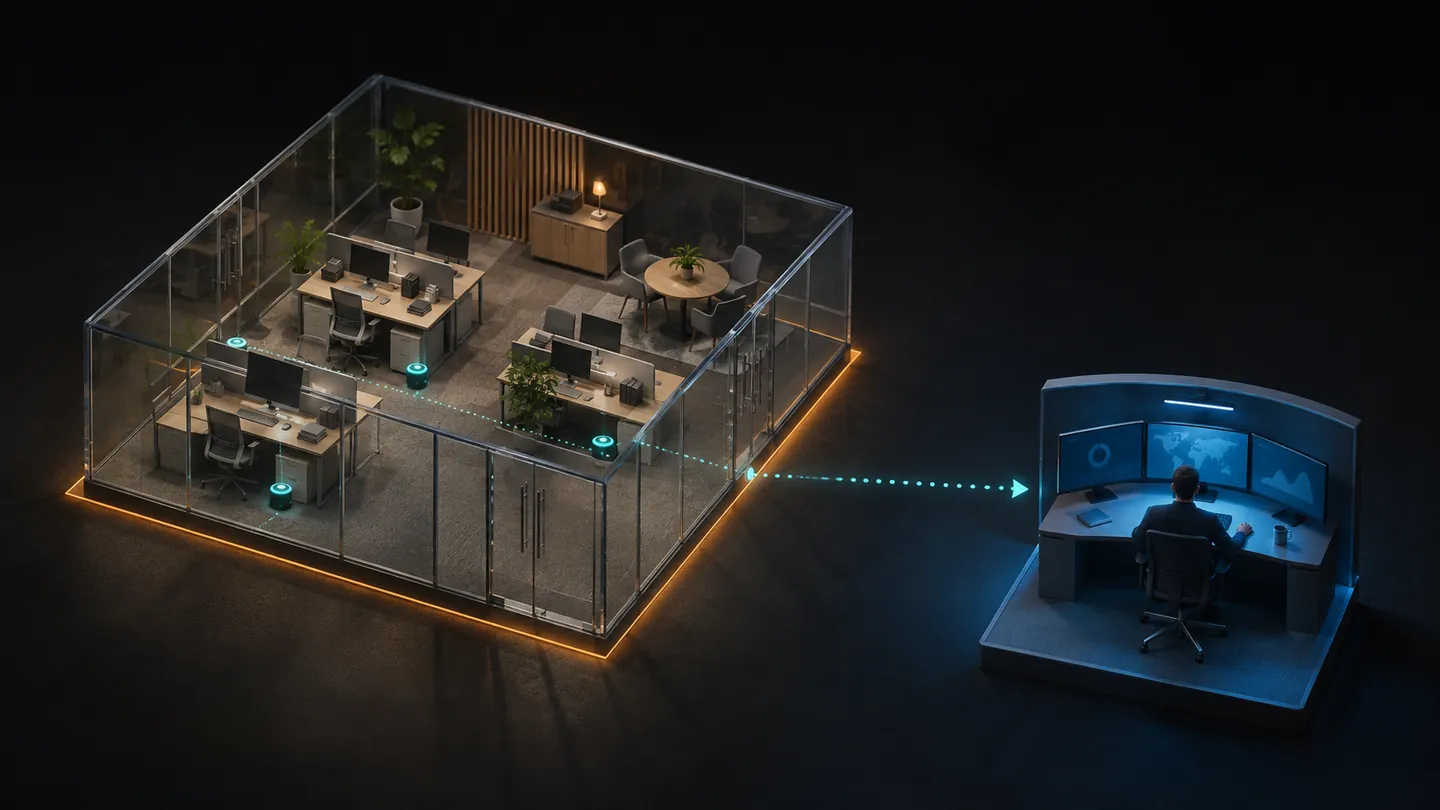
At 8:42, a records folder in a company's spare office registers an access event. Nobody works in that office. No customer files live there. The event is interesting because it is unexpected, but the case still needs a human. A scheduled exercise or a noisy health check could explain it. The decoy's job is to give the analyst a better question to ask.
What changed outside the lab
In October 2026, Microsoft reported that a threat actor it calls Storm-0940 used agentic tooling in a campaign involving privileged cloud access in some organizations. A November follow-up described successful application sign-ins and, in some observed cases, data exfiltration. A sign-in is evidence of authentication, not proof of a data read. A data read is not automatically evidence of exfiltration. These are Microsoft's observations and attribution, not an independent determination by HackWednesday. Neither report tells us how many agents any given operation used or how much human supervision each step had. Microsoft’s October report · Microsoft’s November follow-up.
That evidence supports planning for compressed response times. It does not require the security team to match an attacker action for action. The more useful experiment is whether a defensive team can make a good decision sooner, with fewer mistakes.
Make the decoy feel like an office
A credible decoy has a coherent story. It can represent an office with a made-up directory, department-specific files and plausible activity over time, all generated for the exercise. The labels agree with one another. The facilities inbox does not have the same activity as the finance shelf. The depth is in consistency and context, not in adding a genuine weakness. There are no real credentials, customer records or production privileges. MITRE Engage's defensive scope.
Give it a separate trust boundary. The decoy sends narrowly scoped events to an independent evidence collector; it cannot reach production or issue instructions to the analyst workspace. The evidence collector records provenance and keeps the original events separate from summaries. Treat anything an outsider can put into a record, including apparent instructions, as untrusted text. Keep a human-operated stop mechanism. Nothing follows anyone outside the authorized environment, and there is no hack back.
Give the AI a desk, not the keys
Think of the team like a security operations floor. A triage assistant groups related alerts and flags missing fields. A correlation assistant uses a restricted, read-only copy of approved records to test the leading explanation and its alternatives. A reviewer assistant turns that evidence into a short case for the analyst: observations, uncertainties, links to records and a recommendation. These roles can run in parallel, but shared model output is not independent corroboration.
The human incident lead owns the decision. Agents cannot block an account, change a rule, deploy a patch or reach outside the evidence workspace. In the fictional office above, an assistant might note that a maintenance event preceded the access by two minutes and that identity data is missing for the second event. It should recommend a check and cite both records, not silently declare an intrusion. NIST’s incident-response guidance.
Did the patch actually work?
There are three separate questions. Did the intended change reach the right assets? Does the expected control behave correctly? Do we still see the right signal in monitoring? NIST distinguishes installing a patch from confirming that it has taken effect. A green deployment job answers only part of the first question. NIST’s enterprise patch management guide.
Start with version or configuration evidence for a defined group of assets, including any exceptions. Then use entirely synthetic records in an offline replay: a baseline bundle and a held-out bundle with known expected decisions. The inputs are inert event rows and predefined allow/deny outcomes, not captured requests, exploit code or actual secrets. In the fictional case, an expected access should still be allowed, an out-of-policy event should still be flagged, and a missing log should produce “insufficient evidence.” Run the same records through ordinary monitoring without the assistants for comparison. This replay tests policy interpretation and evidence handling. It cannot establish that a deployed vulnerability is fixed on its own. Use trusted deployment evidence and authorized, non-exploit acceptance checks for that claim.
The downside belongs on the scorecard
Compare ordinary monitoring with the same monitoring plus the read-only assistants. Keep the synthetic cases, expected outcomes and decision criteria the same. Track median time to an evidence-backed decision, missed signals, false escalations, analyst rework minutes and cost per reviewed case. Give the design a stop condition: any boundary violation is a failed run; faster triage does not compensate for weaker evidence or more missed cases.
A high-fidelity decoy should help defenders explain what happened, what remains unknown, and whether the fix has independent evidence behind it. If it adds more confidence than evidence, leave it in the lab.
Source notes
Follow these links to check the reporting and documentation behind this article.
- Microsoft Security Research, October 21, 2026: reported agentic tooling and supply-chain compromise
- Microsoft Threat Intelligence, November 5, 2026: follow-on credential abuse observations
- MITRE Engage Starter Kit: defensive engagement and scope
- NIST SP 800-40 Rev. 4: Guide to Enterprise Patch Management Planning
- NIST SP 800-61 Rev. 3: Incident Response Recommendations and Considerations